AI infrastructure
One stack.Cloud, rack, or data center.
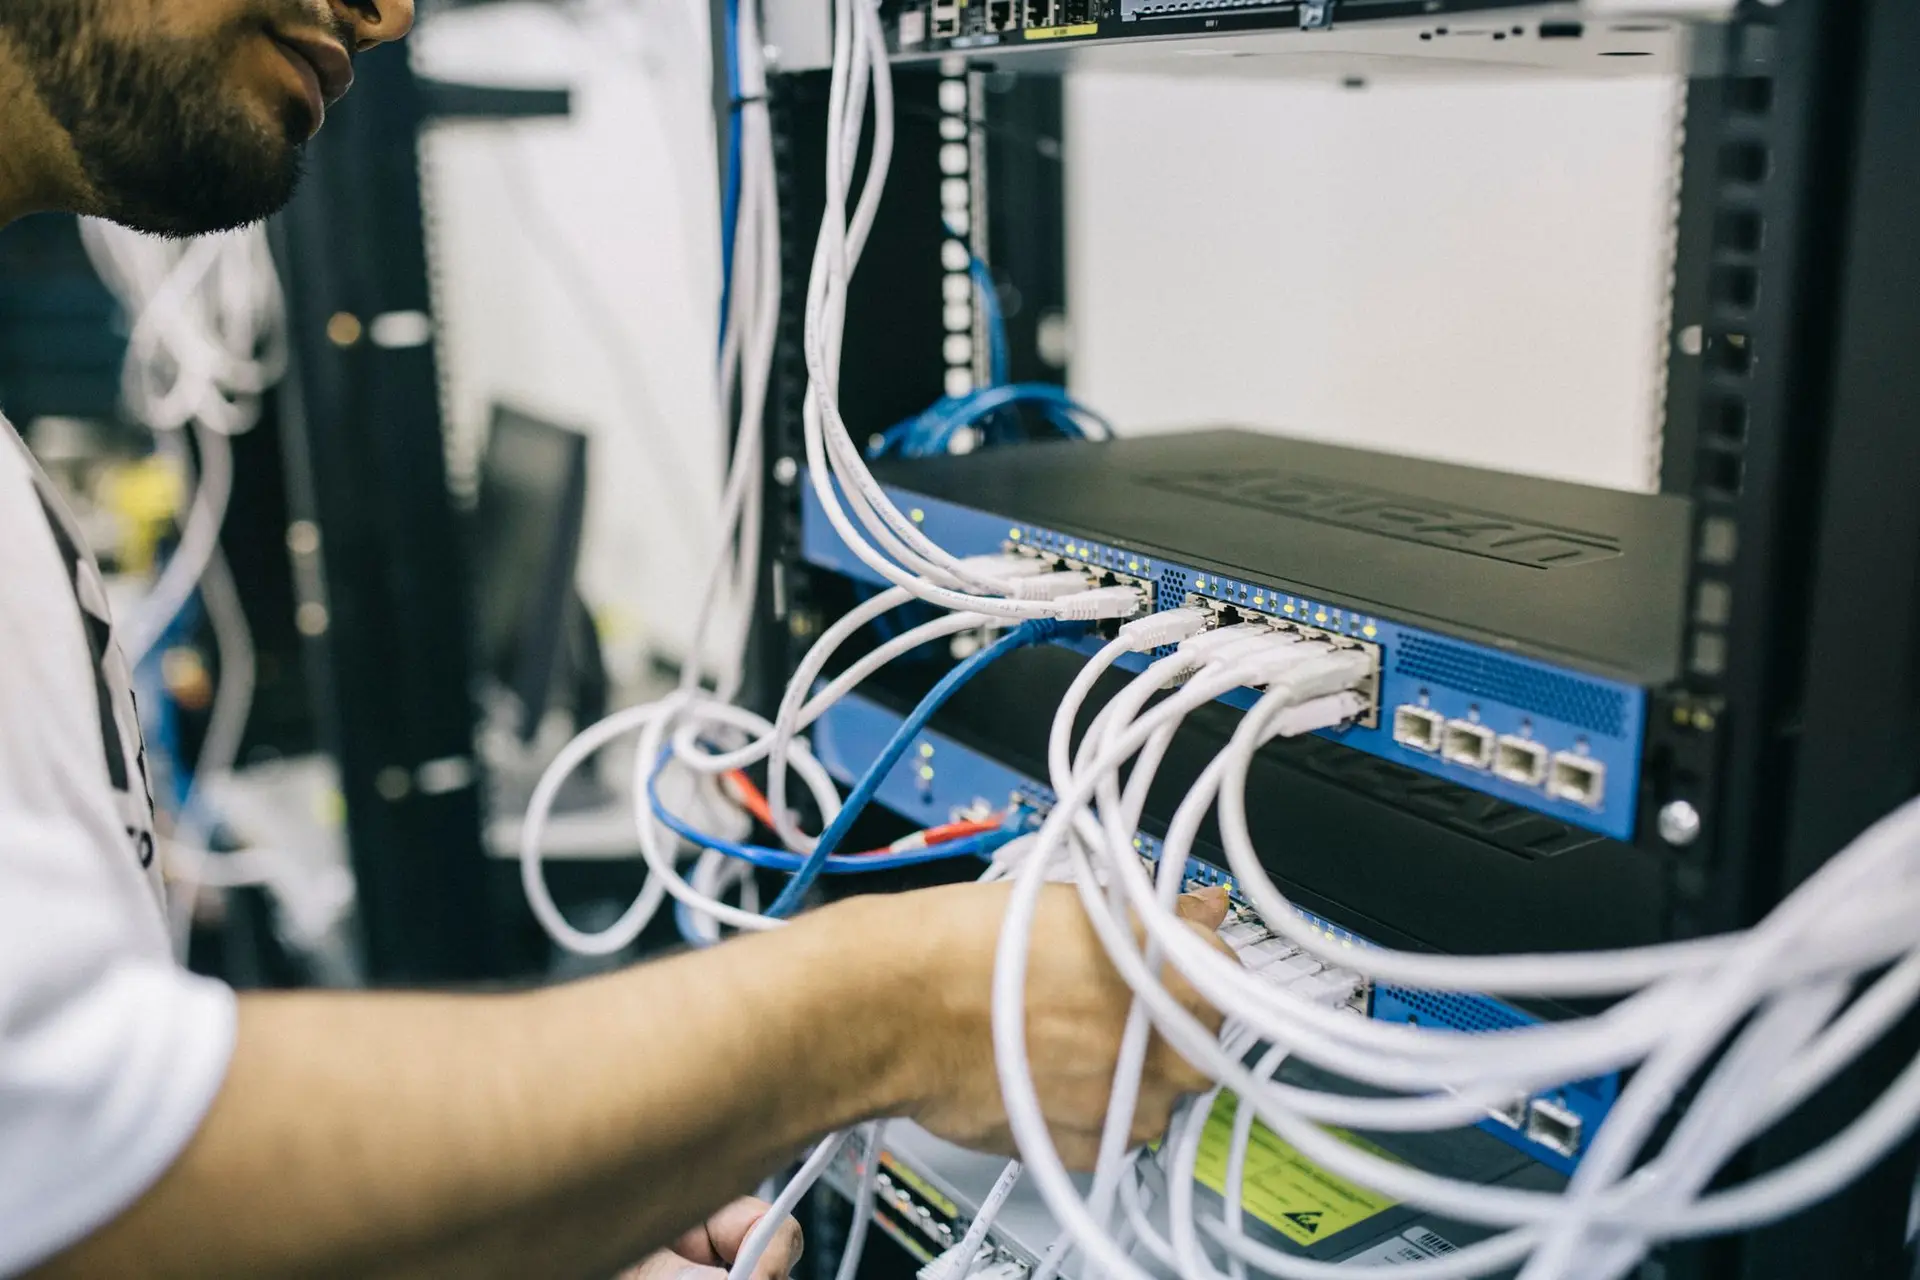
We design, build, and operate the infrastructure AI runs on, and we are equally at home in an AWS account and a server room. Hyperscale cloud, GPU racks on your premises, edge nodes in the field, or a small data center built to order. Placement follows the workload, not the other way around.
The same platform, wherever it has to live.
Every placement ships with the same layered guardrails around the infrastructure: identity, scoped permissions, approvals, and audit, so AI agents act only within the access you grant.
Owned AI capacity, without a facility project.
For organizations that want their models and data under their own roof but do not want to become a data center operator. We deliver a complete, operable installation from one rack up to a small room, and either run it or hand it over.

- Footprint
- 1 to 4 racks, 42U
- Compute
- 2 to 8 GPU nodes per rack (H100, H200, L40S, RTX)
- Fabric
- 100 to 400G Ethernet, InfiniBand on request
- Storage
- NVMe tier for models and datasets, object tier for archives
- Power and cooling
- 10 to 40 kW per rack, air or rear door cooled
- Management
- Out of band access, monitoring, alerting, runbooks
- Serving
- vLLM, NVIDIA NIM, Ollama, OpenAI compatible endpoint
- Time to first inference
- 6 to 10 weeks from site survey, typical
Typical ranges. Every installation is sized to the workload and the site.
Four steps from site survey to first inference.
- 01
Assess
Workload sizing, site survey, power and cooling budget, network and security review. You get a bill of materials and a cost comparison against cloud.
- 02
Design
Rack layout, airflow, cabling plan, node and fabric selection, failure domains, and the operating model: who does what, on what schedule.
- 03
Build
Procurement, racking, cabling, burn in, cluster bring up, model serving, observability, and acceptance tests against the numbers agreed in step one.
- 04
Operate
Monitoring, patching, capacity planning, and on site or remote support, or a handover with runbooks so your team runs it alone.
We will tell you which one is cheaper for you.
Most clients end up with both: cloud for bursts and experiments, owned capacity for the steady production load. The assessment in step one puts numbers on it.
| Cloud | Owned, small data center | |
|---|---|---|
| Best for | Bursty or unpredictable demand, fast starts, global reach | Steady high volume inference, sensitive data, research clusters |
| Time to start | Days | 6 to 10 weeks, typical |
| Cost model | Pay per hour or per token, scales with use | Capital up front, then power and support; pays back on steady load |
| Data residency | Your account, your region | Your building, never leaves |
| Scaling | Elastic, minutes | Planned, add nodes or racks |
| Who operates it | You, with our runbooks, or us | You, with our runbooks, or us |
Built for the workloads the cloud bill cannot justify.
Research and university labs
Shared GPU pools with schedulers and quotas, so a dozen teams stop fighting over cloud credits.
Regulated data
Healthcare, finance, and legal workloads where the model and the data must stay inside the building.
High volume inference
Customer facing assistants and document pipelines where the per token meter has become one of the largest bills.
Studios and creators
Local model hosting for video, audio, and image pipelines next to the edit suite, with no upload wait.
Start with the assessment.
Two weeks, fixed price. You leave with a bill of materials, a site plan, and a cloud versus owned cost comparison you can take to the board.